HashMap in Java – Complete Guide with Internal Working
HashMap is the most used Map implementation in Java. It stores key–value pairs in a hash table, so you can add a value and find it again by its key in constant time on average, whether the map holds ten entries or ten million.
It lives in java.util and has been part of the Collections Framework since JDK 1.2. HashMap is also one of the most popular interview topics, mainly because of how it works inside. This tutorial covers both: everyday use and the internal details of hashing, buckets, collisions and resizing.
1. What Is a HashMap?
Imagine a post office with numbered boxes. A simple rule turns each name into a box number, so the clerk goes straight to the right box instead of searching all of them. HashMap does the same: it turns each key into a bucket number using the key's hash code.
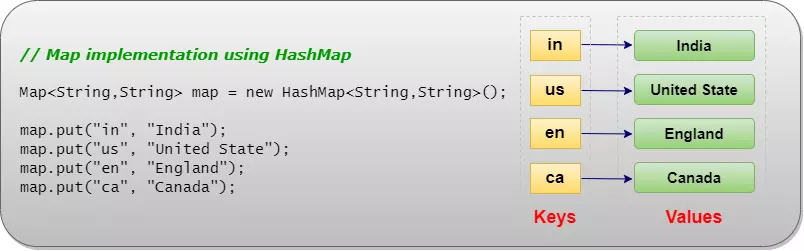
- Unique keys, each mapped to one value; values may repeat.
- No guaranteed order of entries.
- O(1) average
put,get,removeandcontainsKey. - One
nullkey and any number ofnullvalues. - Not synchronized; iterators are fail-fast.
- Default capacity 16, load factor 0.75.
2. Class Hierarchy and Declaration

public class HashMap<K, V> extends AbstractMap<K, V>
        implements Map<K, V>, Cloneable, java.io.Serializable
LinkedHashMap extends HashMap, and HashSet is built on top of it.
3. Your First HashMap Program
import java.util.HashMap;
import java.util.Map;

public class HashMapQuickStart {
    public static void main(String[] args) {
        Map<String, Double> prices = new HashMap<>();

        prices.put("coffee", 120.0);
        prices.put("tea", 60.0);
        prices.put("juice", 90.0);
        System.out.println("Menu:            " + prices);

        prices.put("tea", 70.0);                        // update existing key
        System.out.println("Tea now costs:   " + prices.get("tea"));

        System.out.println("Has juice?       " + prices.containsKey("juice"));
        System.out.println("Removed coffee:  " + prices.remove("coffee"));
        System.out.println("Items left:      " + prices.size());
    }
}Menu: {tea=60.0, coffee=120.0, juice=90.0}
Tea now costs: 70.0
Has juice? true
Removed coffee: 120.0
Items left: 2
Putting a new value for "tea" replaced the old one, because keys are unique. The printed order is not the insertion order.
4. Constructors
| Constructor | What it does |
|---|---|
HashMap() | Empty map, capacity 16, load factor 0.75. |
HashMap(int initialCapacity) | Empty map with room for at least that many buckets (rounded up to a power of two). |
HashMap(int initialCapacity, float loadFactor) | Empty map with the given capacity and load factor. |
HashMap(Map<? extends K, ? extends V> m) | A map with the same entries as m. |
Java 19 added HashMap.newHashMap(int numMappings), which sizes the table so that the given number of entries fits without resizing.
5. Null Keys and Null Values
import java.util.HashMap;
import java.util.Map;

public class HashMapNulls {
    public static void main(String[] args) {
        Map<String, String> nicknames = new HashMap<>();
        nicknames.put(null, "unknown user");   // one null key is allowed
        nicknames.put("Robert", null);         // null values are allowed
        nicknames.put("Elizabeth", "Liz");

        System.out.println("get(null):          " + nicknames.get(null));
        System.out.println("get(Robert):        " + nicknames.get("Robert"));
        System.out.println("get(Sam):           " + nicknames.get("Sam"));
        System.out.println("containsKey(Robert) " + nicknames.containsKey("Robert"));
        System.out.println("containsKey(Sam)    " + nicknames.containsKey("Sam"));
    }
}get(null): unknown user get(Robert): null get(Sam): null containsKey(Robert) true containsKey(Sam) false
get() returned null for both "Robert" (mapped to null) and "Sam" (missing). Only containsKey() tells them apart.
6. How HashMap Works Internally
A HashMap holds an array of buckets called the table. Each bucket holds zero or more nodes, and each node stores four things: the key's hash, the key, the value, and a link to the next node in the same bucket.
put(key, value)
- Hash the key: call
key.hashCode()and spread its bits withh ^ (h >>> 16), so that the high bits also affect the bucket. Anullkey gets hash 0. - Find the bucket:
index = hash & (capacity - 1). Because capacity is always a power of two, this equalshash % capacitybut is faster. - Empty bucket: create a node there.
- Occupied bucket: walk its nodes. If one has the same hash and an
equals()key, replace its value and return the old value. Otherwise add a new node. - Grow if needed: if the number of entries now exceeds
capacity × loadFactor, double the table.
get(key)
Hash the key, go to its bucket, and compare nodes until one matches with equals(). With a good hash function, buckets hold one or two nodes, so this takes constant time.
7. Collisions and Treeification
A collision happens when different keys land in the same bucket. It is normal and handled correctly. The strings "Aa" and "BB" even have the exact same hash code:
import java.util.HashMap;
import java.util.Map;

public class HashMapCollisions {
    static int bucket(Object key, int tableSize) {
        int h = key.hashCode();
        return (h ^ (h >>> 16)) & (tableSize - 1);
    }

    public static void main(String[] args) {
        // "Aa" and "BB" are different strings with the SAME hashCode
        for (String k : new String[] {"Aa", "BB", "Cat", "Dog"}) {
            System.out.printf("%-4s hashCode=%-6d bucket=%d%n", k, k.hashCode(), bucket(k, 16));
        }

        Map<String, Integer> map = new HashMap<>();
        map.put("Aa", 1);
        map.put("BB", 2);                       // same bucket, kept apart by equals()
        System.out.println("get(Aa)=" + map.get("Aa") + ", get(BB)=" + map.get("BB") + ", size=" + map.size());
    }
}Aa hashCode=2112 bucket=0 BB hashCode=2112 bucket=0 Cat hashCode=67510 bucket=7 Dog hashCode=68892 bucket=13 get(Aa)=1, get(BB)=2, size=2
Both keys share bucket 0, and equals() keeps them apart. Since Java 8, when one bucket collects more than 8 nodes (and the table has at least 64 buckets), the bucket's linked list is converted into a red-black tree. That caps the worst-case lookup at O(log n) instead of O(n). When a tree bucket shrinks to 6 nodes or fewer, it turns back into a list.
8. Capacity, Load Factor and Resizing
| Term | Meaning | Default |
|---|---|---|
| Capacity | Number of buckets; always a power of two. | 16 |
| Load factor | How full the table may get before it grows. | 0.75 |
| Threshold | capacity × loadFactor; exceeding it triggers a resize. | 12 |
When the map resizes, the table doubles (16 → 32 → 64 …) and every node moves to its new bucket. Thanks to the power-of-two sizes, each node either stays at the same index or moves exactly oldCapacity places up, so no hash has to be recalculated. Resizing is O(n), but it happens rarely, so put() remains O(1) on average.
The table itself is created lazily, on the first put(), so an empty HashMap costs very little memory.
HashMap.newHashMap(1000) (Java 19+) or new HashMap<>(1334) (1000 / 0.75) to avoid several resizes.9. Using Your Own Classes as Keys
A key class must override equals() and hashCode() consistently, and should be immutable. Records do both automatically:
import java.util.HashMap;
import java.util.Map;

public class HashMapCustomKey {
    // A record is an ideal key: immutable, with equals() and hashCode() generated
    record Seat(char row, int number) { }

    // A plain class without equals()/hashCode()
    static class BadSeat {
        final char row; final int number;
        BadSeat(char row, int number) { this.row = row; this.number = number; }
    }

    public static void main(String[] args) {
        Map<Seat, String> booking = new HashMap<>();
        booking.put(new Seat('A', 12), "Asha");
        System.out.println("Record key lookup:  " + booking.get(new Seat('A', 12)));

        Map<BadSeat, String> badBooking = new HashMap<>();
        badBooking.put(new BadSeat('A', 12), "Asha");
        System.out.println("Plain class lookup: " + badBooking.get(new BadSeat('A', 12)));
    }
}Record key lookup: Asha Plain class lookup: null
The plain class uses identity-based hashCode() and equals(), so a new object with the same data is a different key. Also, never change a key's fields after putting it in the map; its entry would sit in the wrong bucket and become unreachable.
10. Practical Example: Word Frequency
Counting things is one of the most common uses of a HashMap. merge() handles both the first occurrence and later ones:
import java.util.HashMap;
import java.util.Map;

public class WordFrequency {
    public static void main(String[] args) {
        String text = "the cat and the dog and the bird saw the cat";

        Map<String, Integer> freq = new HashMap<>();
        for (String word : text.split(" ")) {
            freq.merge(word, 1, Integer::sum);       // count each word
        }

        System.out.println("Distinct words: " + freq.size());
        System.out.println("Top 3:");
        freq.entrySet().stream()
            .sorted(Map.Entry.<String, Integer>comparingByValue().reversed()
                    .thenComparing(Map.Entry.comparingByKey()))
            .limit(3)
            .forEach(e -> System.out.println("  " + e.getKey() + " = " + e.getValue()));
    }
}Distinct words: 6 Top 3: the = 4 and = 2 cat = 2
11. Iterating, Updating and Removing Safely
Calling map.remove() or map.put() with a new key inside a for-each loop throws ConcurrentModificationException. Use these safe alternatives:
import java.util.HashMap;
import java.util.Iterator;
import java.util.Map;
import java.util.TreeMap;

public class HashMapIterateRemove {
    public static void main(String[] args) {
        Map<String, Integer> stock = new HashMap<>(Map.of("pens", 0, "books", 12, "bags", 0, "caps", 5));

        // Remove out-of-stock items safely
        stock.entrySet().removeIf(e -> e.getValue() == 0);
        System.out.println("In stock:  " + new TreeMap<>(stock));

        // Change values while iterating with Entry.setValue()
        for (Map.Entry<String, Integer> e : stock.entrySet()) {
            e.setValue(e.getValue() + 10);
        }
        System.out.println("Restocked: " + new TreeMap<>(stock));

        // Iterator.remove() also works
        Iterator<String> it = stock.keySet().iterator();
        while (it.hasNext()) {
            if (it.next().startsWith("c")) it.remove();
        }
        System.out.println("No caps:   " + stock);
    }
}In stock: {books=12, caps=5}
Restocked: {books=22, caps=15}
No caps: {books=22}
Replacing the value of an existing key (with setValue() or put()) is not a structural change, so it is allowed during iteration.
12. HashMap and Thread Safety
HashMap is not thread-safe. When several threads update it, updates are lost, and concurrent resizing can corrupt the table. ConcurrentHashMap is the standard replacement: it allows concurrent reads and writes and offers atomic methods such as merge() and compute().
import java.util.HashMap;
import java.util.Map;
import java.util.concurrent.ConcurrentHashMap;

public class ConcurrentCounter {
    public static void main(String[] args) throws InterruptedException {
        Map<String, Integer> safe = new ConcurrentHashMap<>();
        Map<String, Integer> unsafe = new HashMap<>();

        Runnable task = () -> {
            for (int i = 0; i < 100_000; i++) {
                safe.merge("hits", 1, Integer::sum);      // atomic in ConcurrentHashMap
                unsafe.merge("hits", 1, Integer::sum);    // NOT safe in HashMap
            }
        };
        Thread t1 = new Thread(task), t2 = new Thread(task);
        t1.start(); t2.start();
        t1.join();  t2.join();

        System.out.println("ConcurrentHashMap: " + safe.get("hits"));
        System.out.println("HashMap correct?   " + (unsafe.get("hits") == 200_000));
    }
}ConcurrentHashMap: 200000 HashMap correct? false
Other options are Collections.synchronizedMap(new HashMap<>()), which locks the whole map on every call, and the legacy Hashtable.
13. Common HashMap Methods
| Method | Description | Time |
|---|---|---|
put(k, v) | Adds or replaces; returns the old value. | O(1) |
get(k), getOrDefault(k, d) | Reads a value. | O(1) |
remove(k) | Removes an entry; returns its value. | O(1) |
containsKey(k) | Checks for a key. | O(1) |
containsValue(v) | Checks for a value. | O(n) |
putIfAbsent, merge, compute, computeIfAbsent | Conditional and combined updates. | O(1) |
keySet(), values(), entrySet() | Live views for iteration. | O(1) to create |
size(), isEmpty(), clear() | Count, check, empty. | O(1) / O(1) / O(capacity) |
putAll(m) | Copies all entries of another map. | O(m) |
14. HashMap vs Hashtable vs ConcurrentHashMap
| Feature | HashMap | Hashtable | ConcurrentHashMap |
|---|---|---|---|
| Thread-safe | No | Yes (locks whole table) | Yes (fine-grained) |
| null keys / values | One null key, null values | Neither | Neither |
| Performance | Fastest (single thread) | Slow under contention | Fast under contention |
| Iterator | Fail-fast | Fail-fast (Enumeration is not) | Weakly consistent |
| Introduced | JDK 1.2 | JDK 1.0 (legacy) | Java 5 |
15. Best Practices
- Use immutable keys (
String, wrapper types, enums, records). - Override
equals()andhashCode()together in key classes. - Iterate with
entrySet()orforEach, notkeySet()plusget(). - Use
getOrDefault,mergeandcomputeIfAbsentinstead of manual null checks. - Pre-size large maps.
- Never share a HashMap between threads without synchronization; use ConcurrentHashMap.
- Do not rely on iteration order; use LinkedHashMap or TreeMap if order matters.
16. Summary
- HashMap stores unique keys mapped to values in an array of buckets.
- The bucket is chosen from the key's spread hash code;
equals()resolves collisions. - Crowded buckets turn into red-black trees (Java 8+), capping lookups at O(log n).
- Default capacity 16 and load factor 0.75; the table doubles when the threshold is exceeded.
- It allows one
nullkey, is unordered and is not thread-safe.
Related Tutorials
- Map Interface in Java
- LinkedHashMap in Java
- TreeMap in Java
- Difference between HashMap and Hashtable
- Difference between HashSet and HashMap
Reference: Java SE 21 API: java.util.HashMap
Frequently Asked Questions (FAQ)
Q1. What is a HashMap in Java?
HashMap is a class in java.util that implements Map using a hash table. It stores unique keys mapped to values, allows one null key and null values, has no guaranteed order, and gives O(1) average-time put and get.
Q2. How does HashMap work internally?
It keeps an array of buckets. For each key it computes a spread hash (h ^ (h >>> 16)), picks the bucket with hash & (n - 1), and stores a node there. Keys in the same bucket are told apart with equals(). Large buckets become red-black trees, and the table doubles when it gets too full.
Q3. What is the default capacity and load factor of HashMap?
Capacity 16 and load factor 0.75, so the first resize happens when the 13th entry is added (threshold 12).
Q4. Why is HashMap capacity always a power of two?
So the bucket index can be calculated with a fast bitwise AND (hash & (n - 1)) instead of a slower modulo, and so that during resizing each entry either stays put or moves by exactly the old capacity.
Q5. What happens when two keys have the same hash code?
They go into the same bucket (a collision). HashMap stores both nodes in that bucket and uses equals() to find the right one. Equal hash codes never cause one key to overwrite another unless equals() also returns true.
Q6. What changed in HashMap in Java 8?
Buckets with more than 8 entries (in tables of at least 64 buckets) are converted into red-black trees, so worst-case lookups are O(log n) instead of O(n). Java 8 also simplified the hash-spreading function and added default methods such as merge(), compute() and forEach().
Q7. What is the time complexity of HashMap operations?
get, put, remove and containsKey are O(1) on average and O(log n) in the worst case (Java 8+). containsValue and iteration are O(n), and iteration also depends on the capacity.
Q8. Can HashMap have a null key?
Yes, exactly one. Its hash is treated as 0, so it is always stored in bucket 0. Any number of values can be null.
Q9. Why must I override both equals() and hashCode() for a HashMap key?
hashCode() chooses the bucket and equals() confirms the match. If you override only equals(), equal keys may land in different buckets and never be compared. If you override only hashCode(), equal keys share a bucket but are still treated as different.
Q10. What happens if a key is changed after it is put in a HashMap?
If the change affects its hash code, the entry stays in the bucket for the old hash. get() then searches a different bucket and returns null, and the entry is effectively lost. Use immutable keys.
Q11. Why is String a popular HashMap key?
String is immutable, overrides equals() and hashCode() correctly, and caches its hash code after the first calculation, so repeated lookups are fast.
Q12. Is HashMap ordered?
No. The iteration order depends on hash codes and the table size, and it can change after a resize. Use LinkedHashMap for insertion order or TreeMap for sorted keys.
Q13. Is HashMap thread-safe?
No. Concurrent updates can lose data or, during resizing, corrupt the internal structure. Use ConcurrentHashMap, or Collections.synchronizedMap() for simple cases.
Q14. What is the difference between HashMap and Hashtable?
Hashtable is a synchronized legacy class (JDK 1.0) that does not allow null keys or values. HashMap is unsynchronized, faster, allows one null key and null values, and is part of the modern Collections Framework.
Q15. What is the difference between HashMap and ConcurrentHashMap?
ConcurrentHashMap is thread-safe without locking the whole map, offers atomic compound operations, and has weakly consistent iterators that never throw ConcurrentModificationException. It does not allow null keys or values.
Q16. What is the difference between HashMap and HashSet?
HashMap stores key–value pairs; HashSet stores single values. Internally a HashSet uses a HashMap, storing each element as a key with a dummy value.
Q17. What does rehashing mean in HashMap?
When the number of entries exceeds the threshold, HashMap allocates a table twice as large and moves every entry to its bucket in the new table. This is called resizing or rehashing.
Q18. How do I sort a HashMap by its values?
Map<String, Integer> sorted = map.entrySet().stream()
    .sorted(Map.Entry.comparingByValue())
    .collect(Collectors.toMap(Map.Entry::getKey, Map.Entry::getValue,
                              (a, b) -> a, LinkedHashMap::new));
The LinkedHashMap keeps the sorted order.
Q19. How do I remove entries from a HashMap while iterating?
Use map.entrySet().removeIf(...), map.values().removeIf(...), or an explicit iterator's remove(). Calling map.remove() inside a for-each loop throws ConcurrentModificationException.
Q20. Why is the load factor 0.75?
It is a good trade-off between memory and speed. A lower value wastes more empty buckets; a higher value saves memory but causes more collisions and slower lookups. With 0.75, the average bucket holds very few entries.